LingBot-World
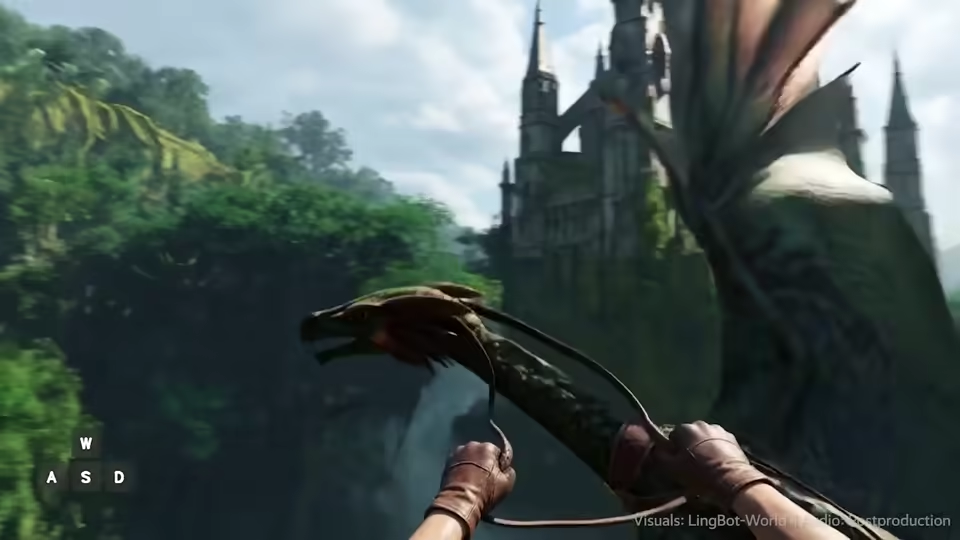
Introduced by Robbyant, LingBot-World is a camera-controllable image-to-video (I2V) world model with streaming inference and context-parallel runtime support. This page covers the original LingBot-World v1 and the causal-fast LingBot-World v2 checkpoints in 14B and 1.3B sizes.
Quick Start
Cam2V
uv sync --package flashdreams-lingbot --inexact
uv run --no-sync flashdreams-run-v2 cam2v-lingbot \
  --mode webrtc --host 0.0.0.0 --port 8089 -- --example-data

# `--example-data` downloads `image.jpg`,
# `intrinsics.npy`, `poses.npy`, and `prompt.txt` from the
# canonical examples folder: https://github.com/Robbyant/lingbot-world-v2/tree/main/examples
Demo Presets
Cam2V
| Preset | Description |
|---|---|
cam2v-lingbot |
Compatibility alias for the bounded-window TAEHV default. |
cam2v-lingbot-world-fast |
LingBot-World v1 with the Wan VAE decoder and full KV cache. |
cam2v-lingbot-world-fast-taehv-window15-sink3 |
LingBot-World v1 with TAEHV and bounded streaming KV cache. |
cam2v-lingbot-world-v2-14b-causal-fast |
LingBot-World v2 14B causal-fast with the Wan VAE decoder. |
cam2v-lingbot-world-v2-14b-causal-fast-taehv-window15-sink3 |
LingBot-World v2 14B causal-fast with TAEHV and bounded streaming KV cache. |
cam2v-lingbot-world-v2-1p3b-causal-fast-perf |
LingBot-World v2 1.3B tuned for RTX 5090-class GPUs with row-wise FP8 and in-tree Sage attention. |
cam2v-lingbot-world-v2-1p3b-causal-fast-perf-taehv |
The 1.3B performance preset with TAEHV decoding. |
Developer Details
- Minimum VRAM: about 120 GB for the 14B presets; the 1.3B performance presets target 32 GB RTX 5090-class GPUs.
- PyTorch: 2.9 or newer.
- Disk: keep ~200 GB free for the 14B model and Hugging Face cache.
- First launch: a few minutes (download, compilation, Triton autotuning, and CUDA-graph warmup). Subsequent launches reuse the caches.
The 1.3B performance presets use row-wise FP8 linear layers and the in-tree
sage attention backend; they do not require the external SageAttention
package. The TAEHV variant replaces the Wan VAE decoder. These paths were
validated on Linux with an RTX 5090; exclude compilation warmup from
steady-state benchmarks.
Performance (Outdated)
Here is the profiling benchmark on total DiT runtime for FlashDreams LingBot-World compared to the official LingBot-World implementation and LightX2V under matched settings.
Samples
Citation
If you use LingBot-World, please cite the original work:
@article{lingbot-world,
      title={Advancing Open-source World Models},
      author={Robbyant Team and Zelin Gao and Qiuyu Wang and Yanhong Zeng and Jiapeng Zhu and Ka Leong Cheng and Yixuan Li and Hanlin Wang and Yinghao Xu and Shuailei Ma and Yihang Chen and Jie Liu and Yansong Cheng and Yao Yao and Jiayi Zhu and Yihao Meng and Kecheng Zheng and Qingyan Bai and Jingye Chen and Zehong Shen and Yue Yu and Xing Zhu and Yujun Shen and Hao Ouyang},
      journal={arXiv preprint arXiv:2601.20540},
      year={2026}
}