FlashVSR
FlashVSR is a one-diffusion-step streaming diffusion framework for real-time video super-resolution (VSR). It combines a train-friendly three-stage distillation pipeline, locality-constrained sparse attention that bridges the train-test resolution gap, and a tiny conditional decoder for fast reconstruction.

Quick Start
V2V
uv sync --package flashdreams-flashvsr --inexact
uv run --no-sync flashdreams-run-v2 \
  v2v-flashvsr-v1.1-sparse-ratio-2.0 \
  --output-path artifacts/flashvsr.mp4 --timeout unbound -- --video-path input.mp4
Demo Presets
V2V
| Preset | Description |
|---|---|
v2v-flashvsr-v1.1-sparse-ratio-2.0 |
Stable sparse-attention 2x video super-resolution. |
v2v-flashvsr-v1.1-sparse-ratio-1.5 |
Faster sparse-attention 2x video super-resolution. |
v2v-flashvsr-v1.1-full-attn |
Dense full attention with multi-GPU context-parallel support. |
Developer Details
- Minimum VRAM: about 24 GB.
- Python: 3.10 or newer.
- PyTorch: 2.9 or newer.
Post-processing presets
Cam2V and Interactive Drive commands select these presets with
--postprocess-preset PRESET in their application arguments, after --:
| Preset | Description |
|---|---|
flashvsr-v1.1-sparse-2.0 |
N/A |
flashvsr-v1.1-sparse-1.5 |
N/A |
flashvsr-v1.1-full-attn |
N/A |
Performance (Outdated)
This historical benchmark compares per-chunk 2x upsampling time for FlashDreams FlashVSR with the official FlashVSR implementation under matched settings.
Samples
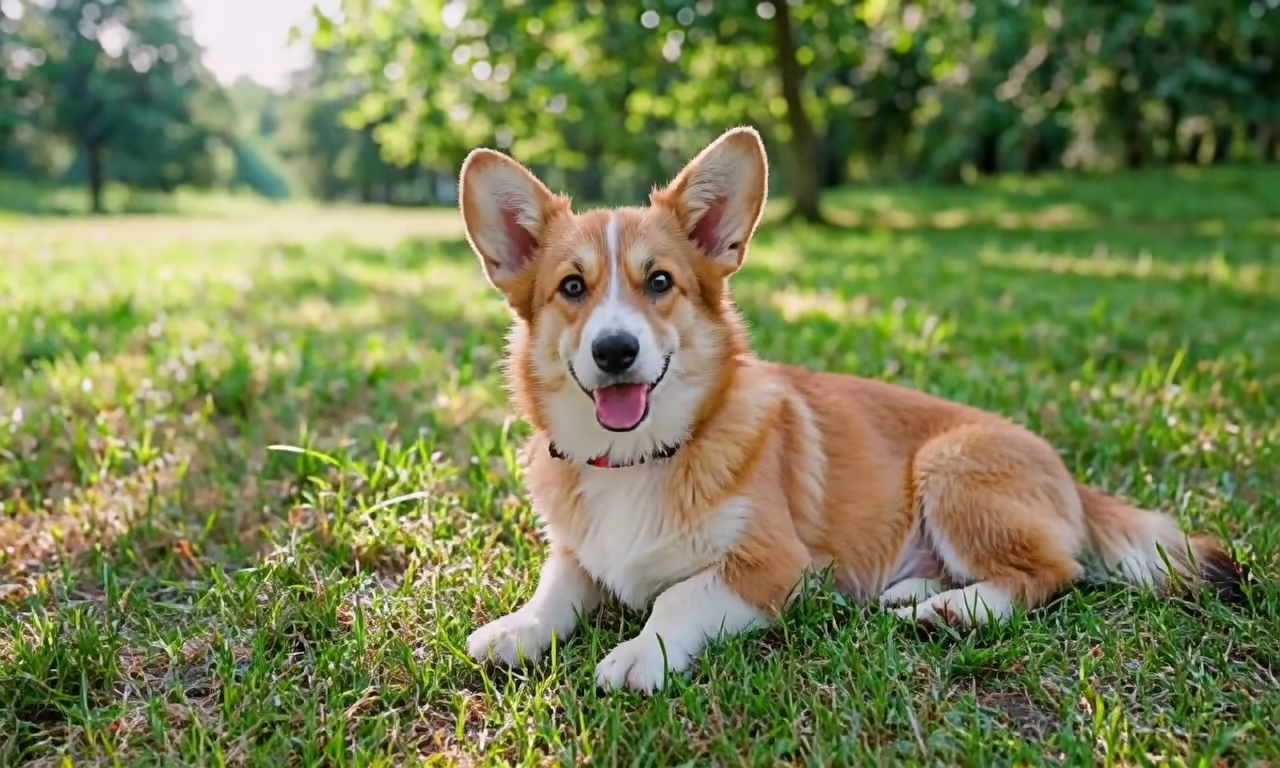
flashvsr-v1.1-sparse-ratio-2.0;
low-resolution input (672x384) inset at bottom-left.
Input from the
FlashVSR examples.
Citation
If you use FlashVSR, please cite the original work:
@inproceedings{zhuang2026flashvsr,
  title={FlashVSR: Towards Real-time Diffusion-Based Streaming Video Super Resolution},
  author={Zhuang, Junhao and Guo, Shi and Cai, Xin and Li, Xiaohui and Liu, Yihao and Yuan, Chun and Xue, Tianfan},
  booktitle={Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition},
  pages={43482--43493},
  year={2026}
}